01
Bengali and low-resource NLP
Benchmarks and methods for language technologies where data and evaluation resources remain limited.
Research portfolio · Dhaka, Bangladesh
I'm Khan Raiyan Ibne Reza, a computer science graduate of North South University. I build benchmarks and AI systems to study how well language and multimodal models use evidence in low-resource settings.
Khan Raiyan Ibne Reza
Computer science · Bengali and low-resource AI
Research focus
01
Benchmarks and methods for language technologies where data and evaluation resources remain limited.
02
How query language, evidence quality, and knowledge structure shape retrieval and grounded answers.
03
Evaluation of visual and document reasoning, alongside compact models for offline educational use.
Accepted papers
Bangla-English tutoring requires more than producing a correct translation: learners also need explanations of grammar differences, awareness of their likely errors, and targeted practice. We present TRACE-BN, a curriculum-guided dataset of 4,099 structured tutoring traces for Bangla-speaking learners of English at the CEFR A1–A2 level across 13 NCTB grammar units and 15 situational domains. Each trace encodes seven multi-task fields: word-level glosses, literal translation, natural translation, Bangla contrastive grammar notes, a common learner mistake, a practice question, and its answer. We transfer this multi-component tutoring behavior to Qwen3-0.6B using LoRA with 4-bit quantization (378.3 MB GGUF) for offline, on-device deployment. On 432 held-out examples, schema validity improves from 85.4% to 95.8%, chrF++ rises from 15.28 to 34.77 (+19.49 gain), and BLEU increases from 4.52 to 21.03, supported by dual automated judges and a 100-trace educator audit (4.71/5.00 overall rating).
11th IEEE Asia-Pacific Conference on Computer Science and Data Engineering (IEEE CSDE 2026)
PhysicsMate is a curriculum-grounded Bengali benchmark for secondary-school physics question answering, built from the NCTB Grade 9–10 syllabus. It contains 1,834 question-answer pairs grounded in a multi-relational knowledge graph with 1,760 nodes and 2,600 edges. Small-model adaptation across 0.6B, 1.7B, and 4B parameter scales improves closed-book accuracy by 5.5, 15.0, and 23.3 percentage points, respectively, supporting offline educational use in settings with limited connectivity and hardware.
11th IEEE Asia-Pacific Conference on Computer Science and Data Engineering (IEEE CSDE 2026)
This work studies how chunking and record structure affect Bengali retrieval-augmented systems and agent memory. It compares chunked text, intact full-node text, and field-structured retrieval across agricultural, legal, and secondary-education domains, examining both retrieval quality and downstream evidence grounding.
Third Workshop on KNOwledge GRaphs & Agentic Systems Interplay (NORA), AACL-IJCNLP 2026
Selected projects
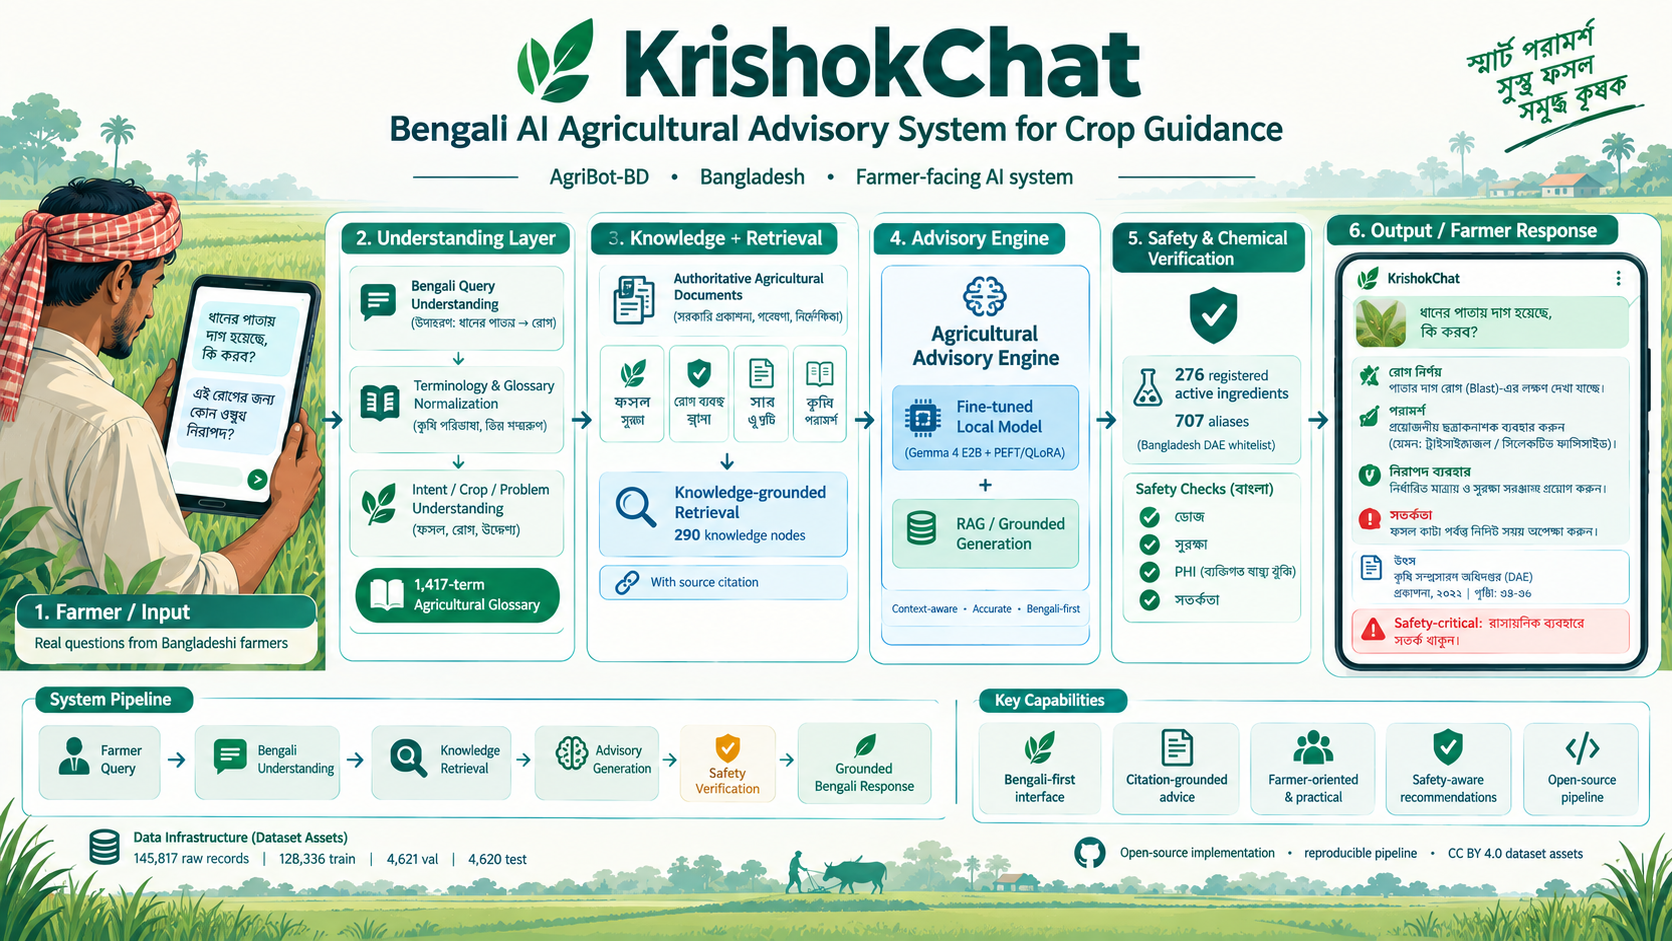
Safety-aware Bengali agricultural advisory RAG with crop disease vision diagnostics.
85,979 Instances
Benchmark Scale
88% Accuracy
Wheat Sweep
99.8% Recall
Crop Sweep
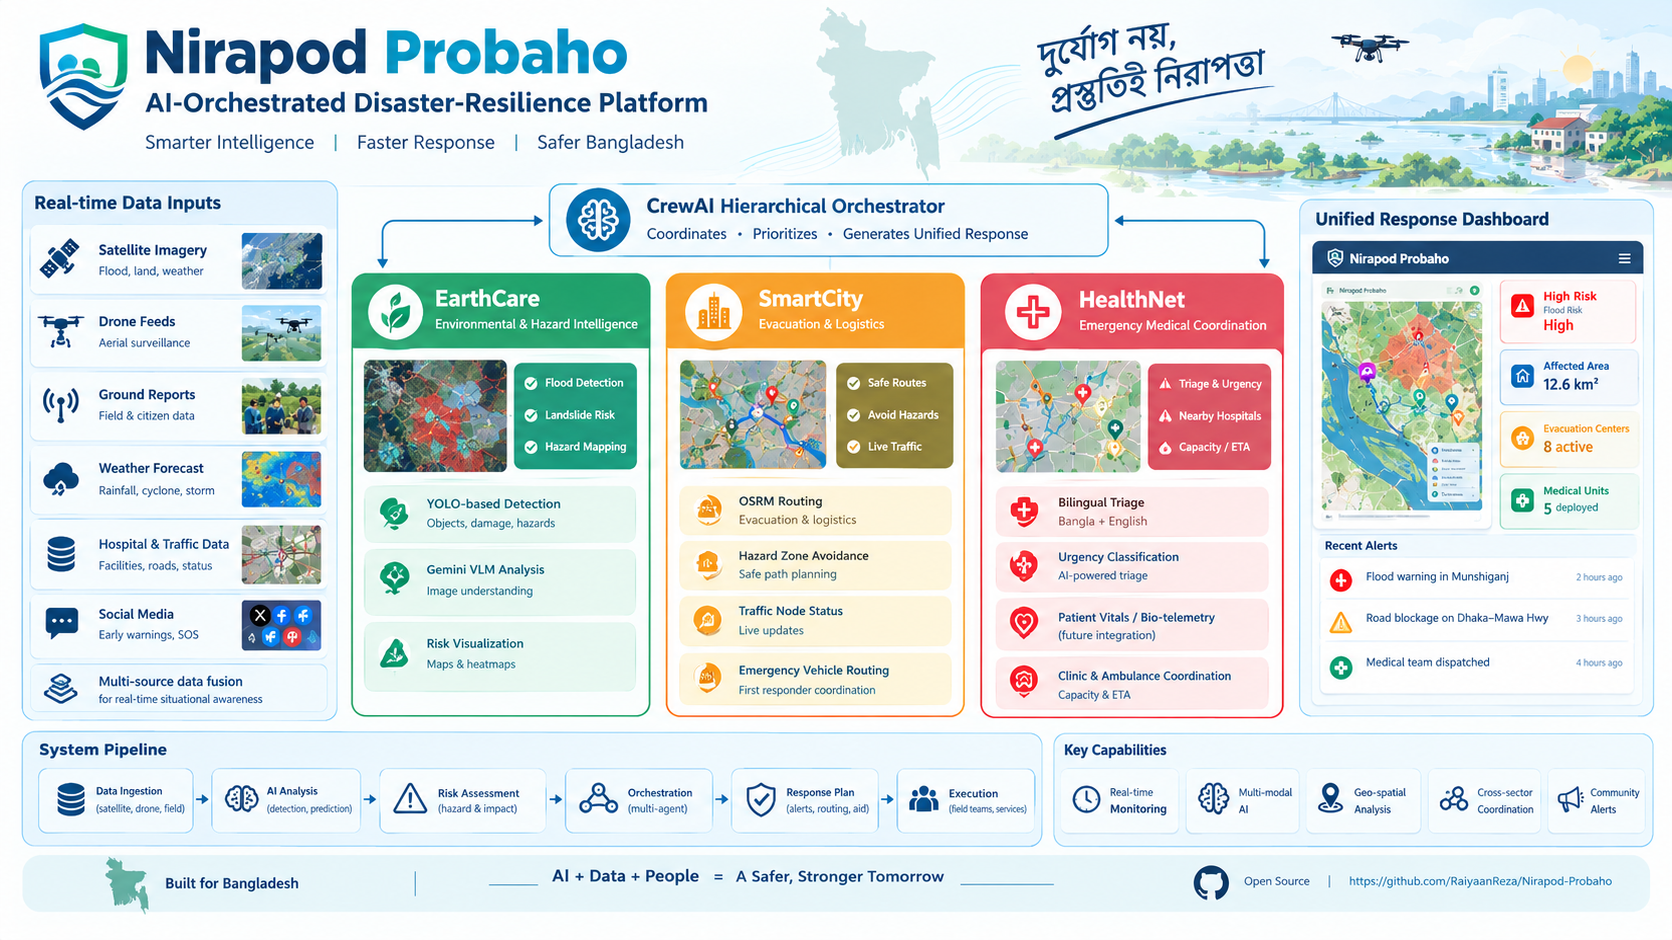
AI-orchestrated multi-agent disaster resilience and relief distribution platform.
4 Multi-Agent Roles
Agent Crew
14.2s → 3.4s
Triage Latency
PostGIS + MapLibre
Spatial Engine
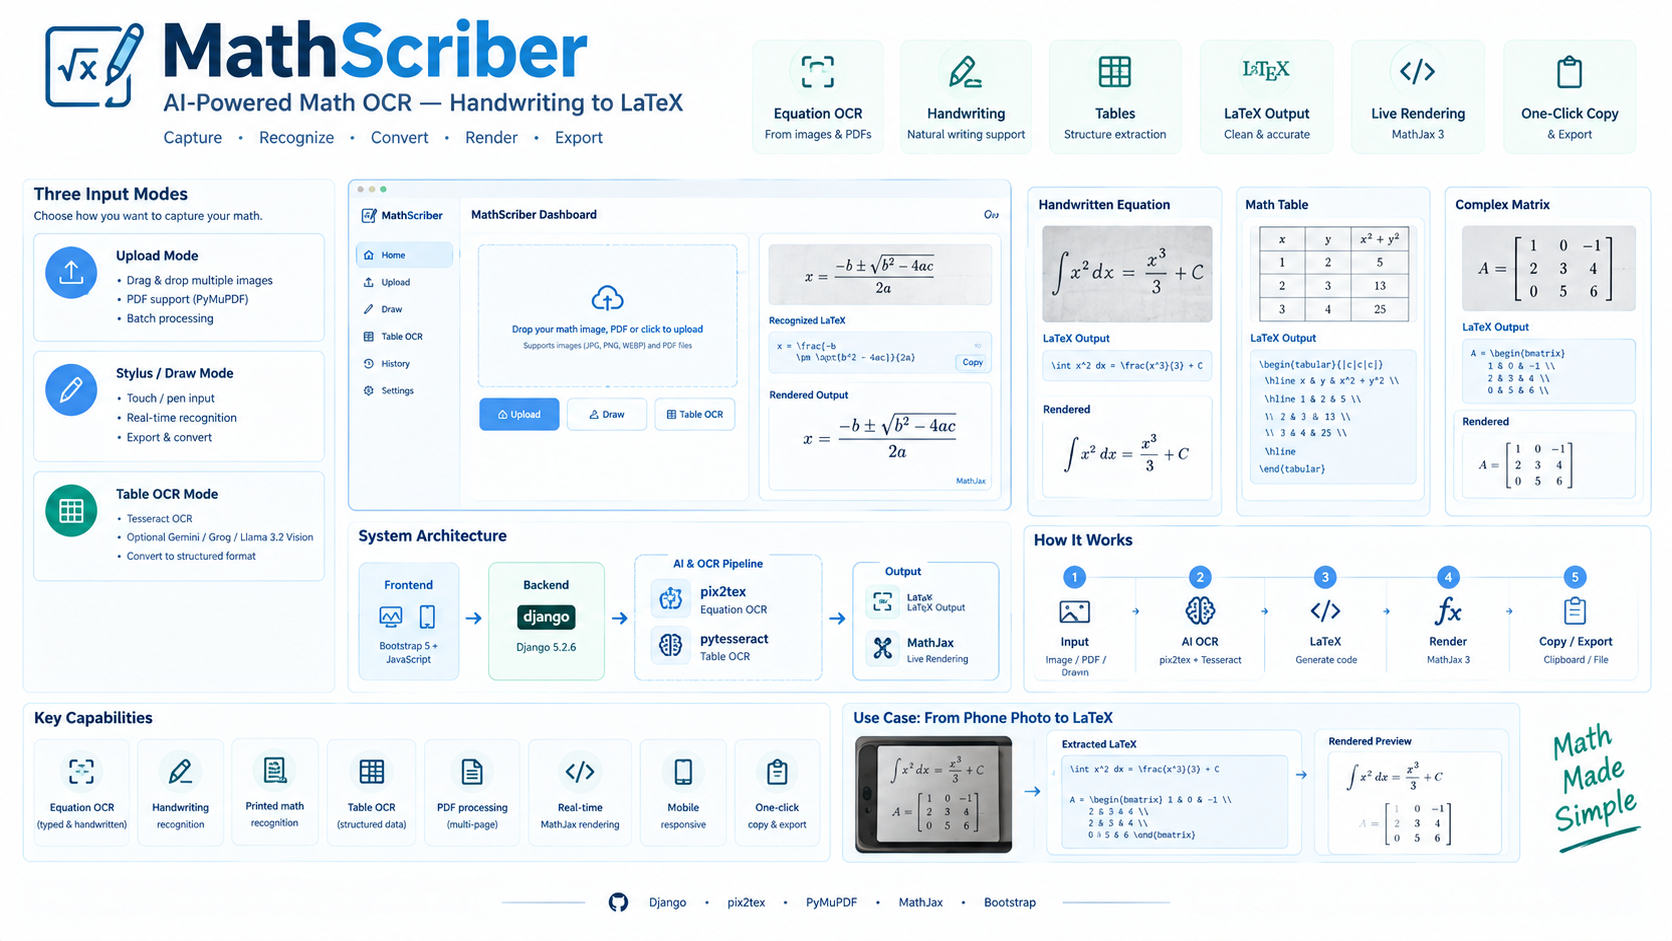
Handwritten math diagram and formula OCR-to-LaTeX converter.
pix2tex Transformer
Vision Model
MathJax Real-Time
Rendering
Open research resources
Browse reusable Bengali datasets and models, or get in touch about a paper or collaboration.