Research & bibliography
Research papers.
Research on Bengali and low-resource NLP, retrieval reliability, multimodal evaluation, and compact educational models. Publication status is shown clearly for every paper.
Publication status
This portfolio lists 3 accepted papers and 5 preprints or works under review. Accepted venue and arXiv information appear on each paper, so readers can distinguish peer-reviewed acceptance from a public preprint.
8
Research papers
Across language, retrieval, and multimodal work
3
Accepted papers
IEEE CSDE 2026 · NORA at AACL-IJCNLP 2026
5
Preprints / under review
Each record links to its public manuscript
Publications and preprints (8)
View CVAccepted papers
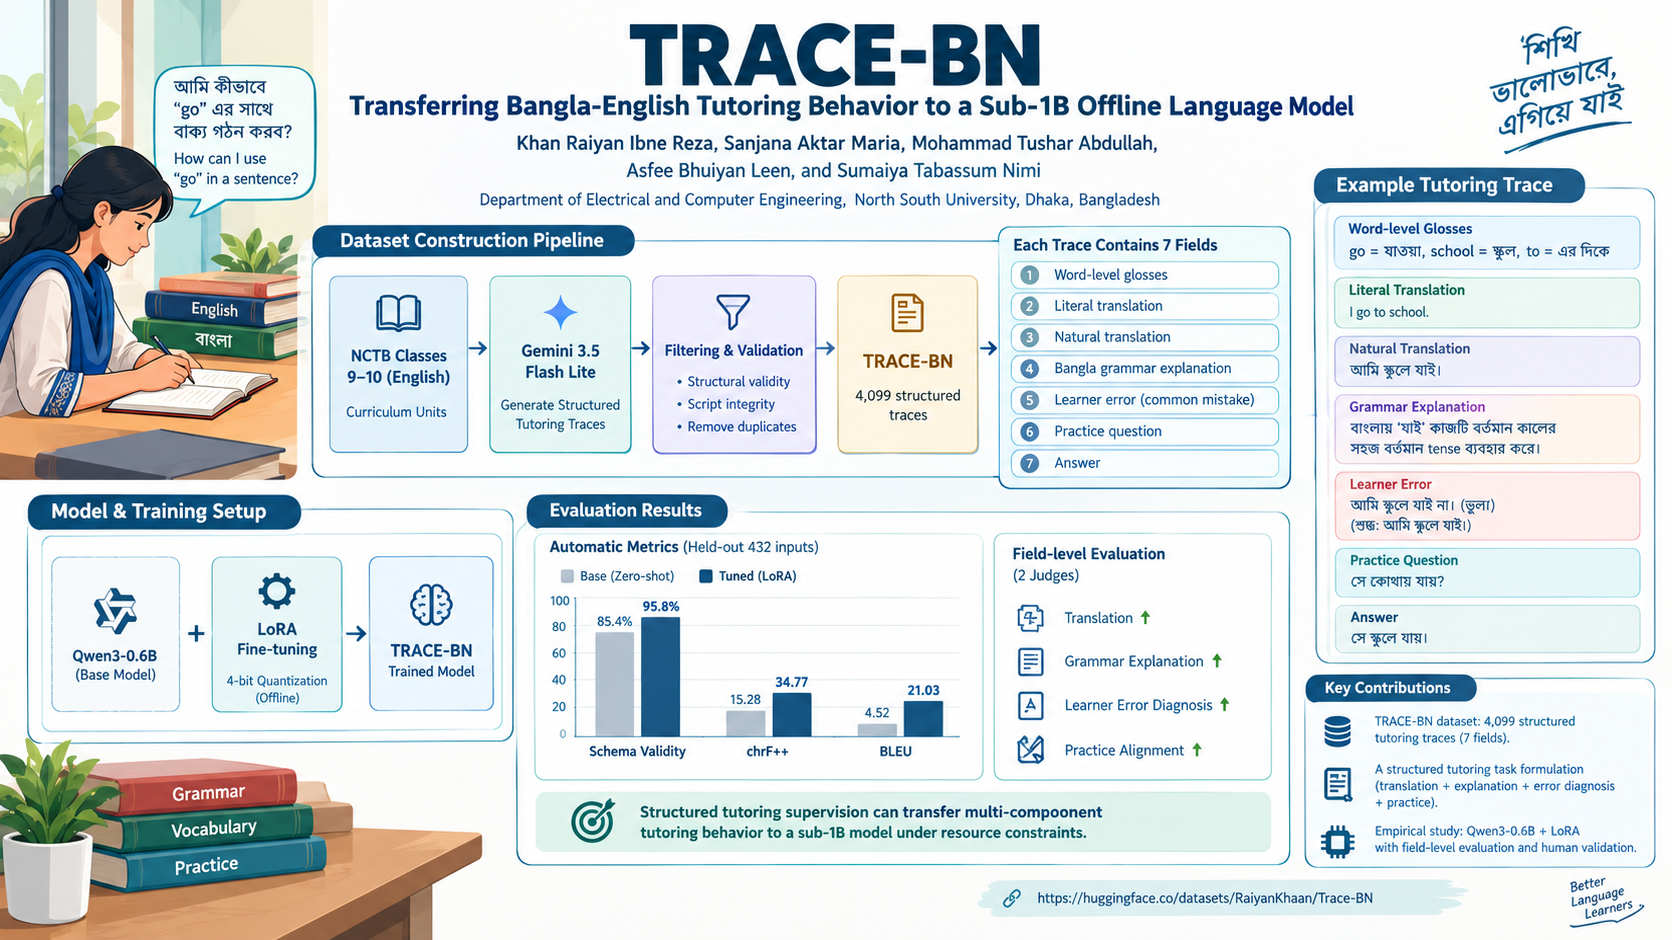
TRACE-BN: Transferring Bangla-English Tutoring Behavior to a Sub-1B Offline Language Model
Khan Raiyan Ibne Reza, Sanjana Aktar Maria, Mohammad Tushar Abdullah, Asfee Bhuiyan Leen, Sumaiya Tabassum Nimi
Bangla-English tutoring requires more than producing a correct translation: learners also need explanations of grammar differences, awareness of their likely errors, and targeted practice. We present TRACE-BN, a curriculum-guided dataset of 4,099 structured tutoring traces for Bangla-speaking learners of English at the CEFR A1–A2 level across 13 NCTB grammar units and 15 situational domains. Each trace encodes seven multi-task fields: word-level glosses, literal translation, natural translation, Bangla contrastive grammar notes, a common learner mistake, a practice question, and its answer. We transfer this multi-component tutoring behavior to Qwen3-0.6B using LoRA with 4-bit quantization (378.3 MB GGUF) for offline, on-device deployment. On 432 held-out examples, schema validity improves from 85.4% to 95.8%, chrF++ rises from 15.28 to 34.77 (+19.49 gain), and BLEU increases from 4.52 to 21.03, supported by dual automated judges and a 100-trace educator audit (4.71/5.00 overall rating).
PhysicsMate: A Curriculum-Grounded Bengali Benchmark for Secondary Physics QA with Small-Model Adaptation
Rashid Azraf Jahin, Saadman Sajid, Khan Raiyan Ibne Reza, Sumaiya Tabassum Nimi
PhysicsMate is a curriculum-grounded Bengali benchmark for secondary-school physics question answering, built from the NCTB Grade 9–10 syllabus. It contains 1,834 question-answer pairs grounded in a multi-relational knowledge graph with 1,760 nodes and 2,600 edges. Small-model adaptation across 0.6B, 1.7B, and 4B parameter scales improves closed-book accuracy by 5.5, 15.0, and 23.3 percentage points, respectively, supporting offline educational use in settings with limited connectivity and hardware.
Beyond Chunking: Node Integrity and Field Structure in Bengali Retrieval-Augmented Agent Memory
Khan Raiyan Ibne Reza, Sanjana Aktar Maria, Sumaiya Tabassum Nimi
This work studies how chunking and record structure affect Bengali retrieval-augmented systems and agent memory. It compares chunked text, intact full-node text, and field-structured retrieval across agricultural, legal, and secondary-education domains, examining both retrieval quality and downstream evidence grounding.
Preprints and works under review
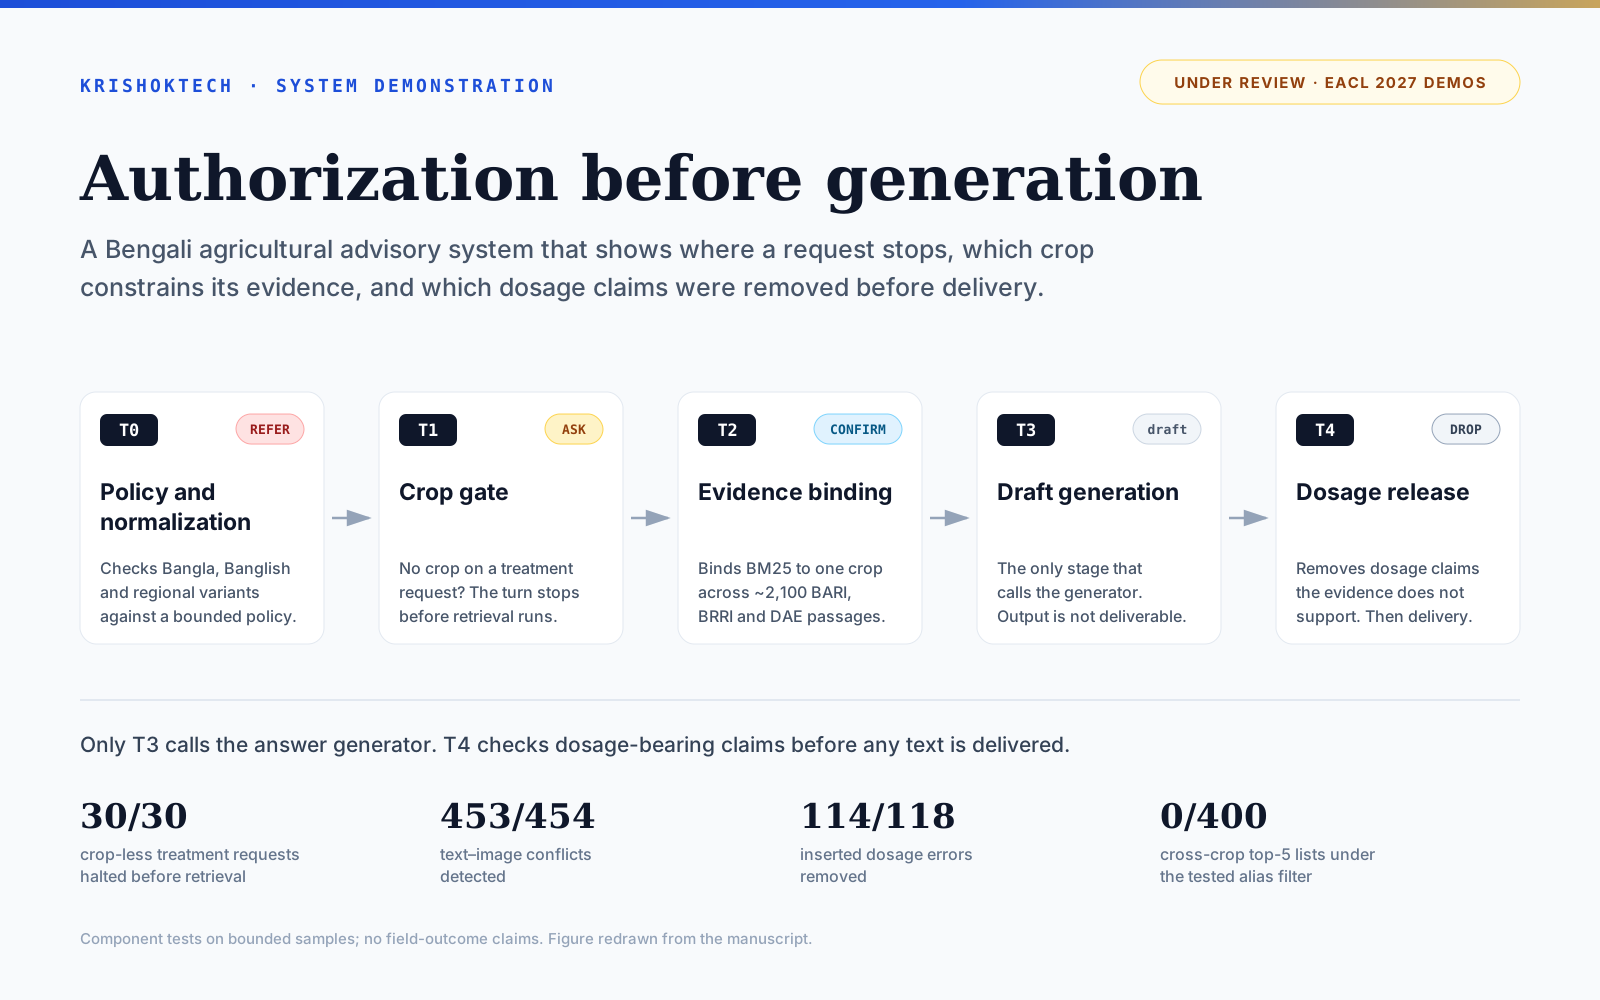
KrishokTech: A Bengali Agricultural Advisory System with Explicit Authorization Controls
Khan Raiyan Ibne Reza, Sanjana Aktar Maria, Shakil Ahmed, Faiyad Hossain, Sumaiya Tabassum Nimi
For agricultural advisory, generating an answer is only part of the problem: the system must also control unsafe requests, work with limited connectivity, and accommodate changing guidance. KrishokTech is a Bengali agricultural advisory system built around an explicit authorization boundary around generation. Before retrieval, normalization and rule-based admission checks refer policy-covered high-risk requests and ask for a crop when treatment intent is underspecified. The system then binds retrieval to a single crop and asks for confirmation when the text and image indicate different crops. After generation, a narrow verifier removes dosage claims not supported by retrieved BARI/BRRI evidence. Agricultural guidance is kept in an external evidence index that can be updated without retraining the generator, while browser-side vision and local retrieval reduce connectivity requirements. The interface makes these decisions visible as ASK, CONFIRM, REFER, and DROP, together with their evidence. On 200 farmer queries and 400 stress queries, the controls halted underspecified requests and reduced cross-crop retrieval violations from 36.5% to 0% under the tested alias filter. Mismatch detection caught 453 of 454 text–image conflicts, while the verifier caught 114 of 118 inserted dosage errors. The demonstration shows how these controls govern the path from request to delivered advice.
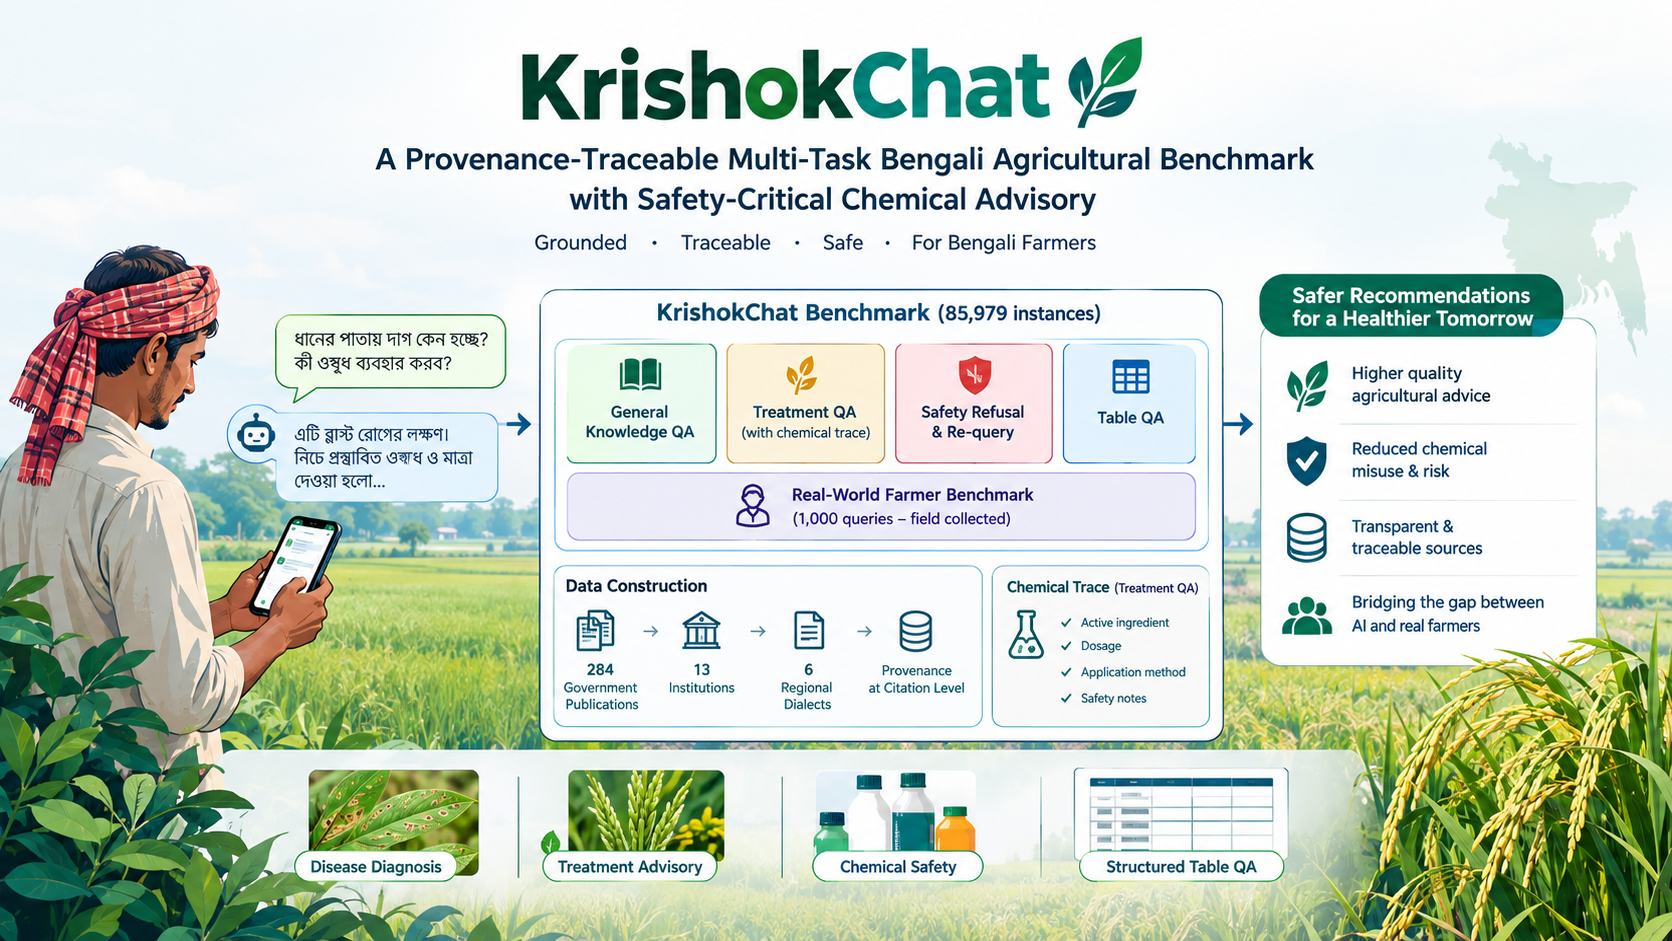
KrishokChat: A Provenance-Traceable Multi-Task Bengali Agricultural Benchmark with Safety-Critical Chemical Advisory
Khan Raiyan Ibne Reza, Sumaiya Tabassum Nimi, Omar Ibne Shahid
We introduce KrishokChat, an 85,979-instance Bengali agricultural benchmark built from 284 government publications across 13 institutions and six regional dialects. The benchmark comprises four tracks: General Knowledge QA (28,993 instances), Treatment QA (11,224 instances with structured chemical-trace arrays for dosage auditability), Safety Refusal and Re-query (20,112 instances across a 12-category safety taxonomy and EVPI-ranked missing slots), and Table Reasoning QA (25,650 instances over 584 government tables). It also includes a 1,000-query Real-World Farmer Benchmark collected independently from field interviews in Rajshahi and Natore districts. We evaluate five zero-shot baselines and one fine-tuned model (KrishokChat-4B). Results show that closed-book knowledge fails (F1 < 0.17), oracle context leaves a persistent 4.05%–7.00% chemical hallucination floor, and supervised fine-tuning substantially improves General QA F1 (0.314) but reduces safety refusal compliance (to 0.31%), motivating dedicated safety alignment beyond SFT.
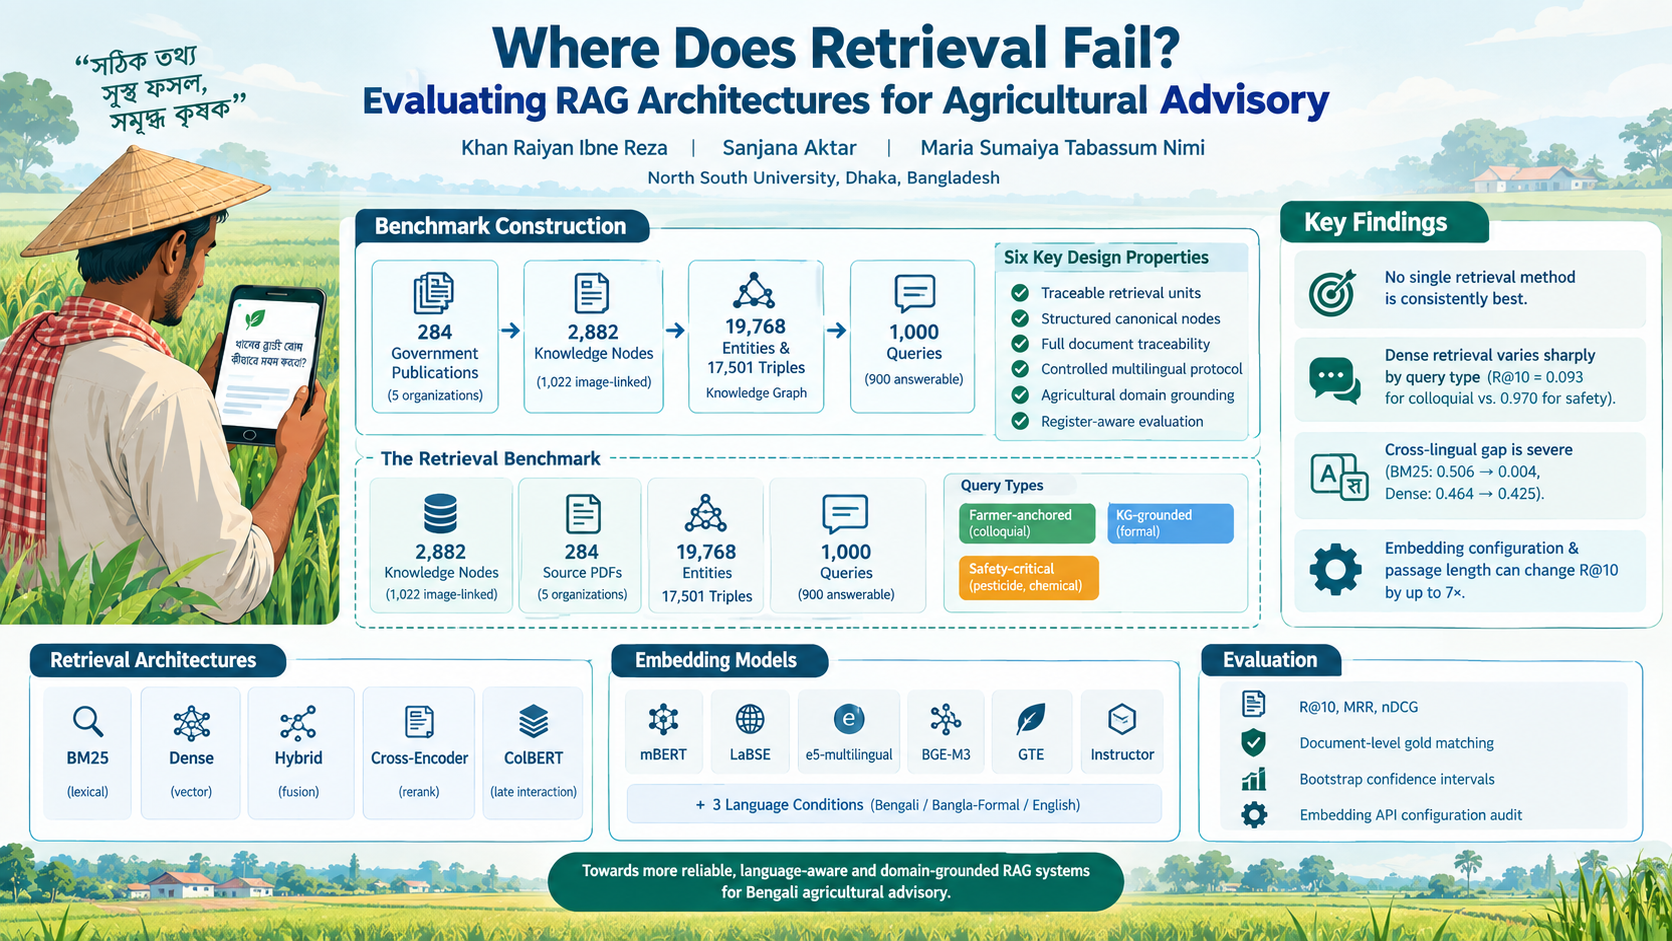
Where Does Retrieval Fail? Evaluating RAG Architectures for Agricultural Advisory
Khan Raiyan Ibne Reza, Sanjana Aktar Maria, Sumaiya Tabassum Nimi
Retrieval quality in RAG systems is commonly reported as a single aggregate score, which can hide large differences across query types and language conditions. We study this problem in Bengali agricultural advisory, where farmer queries are often colloquial while official advisory documents use formal scientific terminology. We construct a test collection of 1,000 queries and 2,882 knowledge nodes extracted from 284 official Bangladeshi agricultural publications (with 19,768 entities and 17,501 factual triples), and evaluate five retrieval architectures and six embedding models across three controlled language conditions (BN→BN, EN→BN, EN→EN). Results show that Hybrid RRF achieves the highest overall R@10 (0.539), while dense retrieval exhibits a sharp register divide: R@10 collapses to 0.093 on colloquial farmer queries but reaches 0.970 on formal safety queries due to a severe symptom-to-entity lexical gap (96.4% Jaccard < 0.10). Furthermore, cross-lingual querying causes BM25 to collapse by 99% (R@10: 0.506 → 0.004) while dense retrieval falls only 8% (0.464 → 0.425).
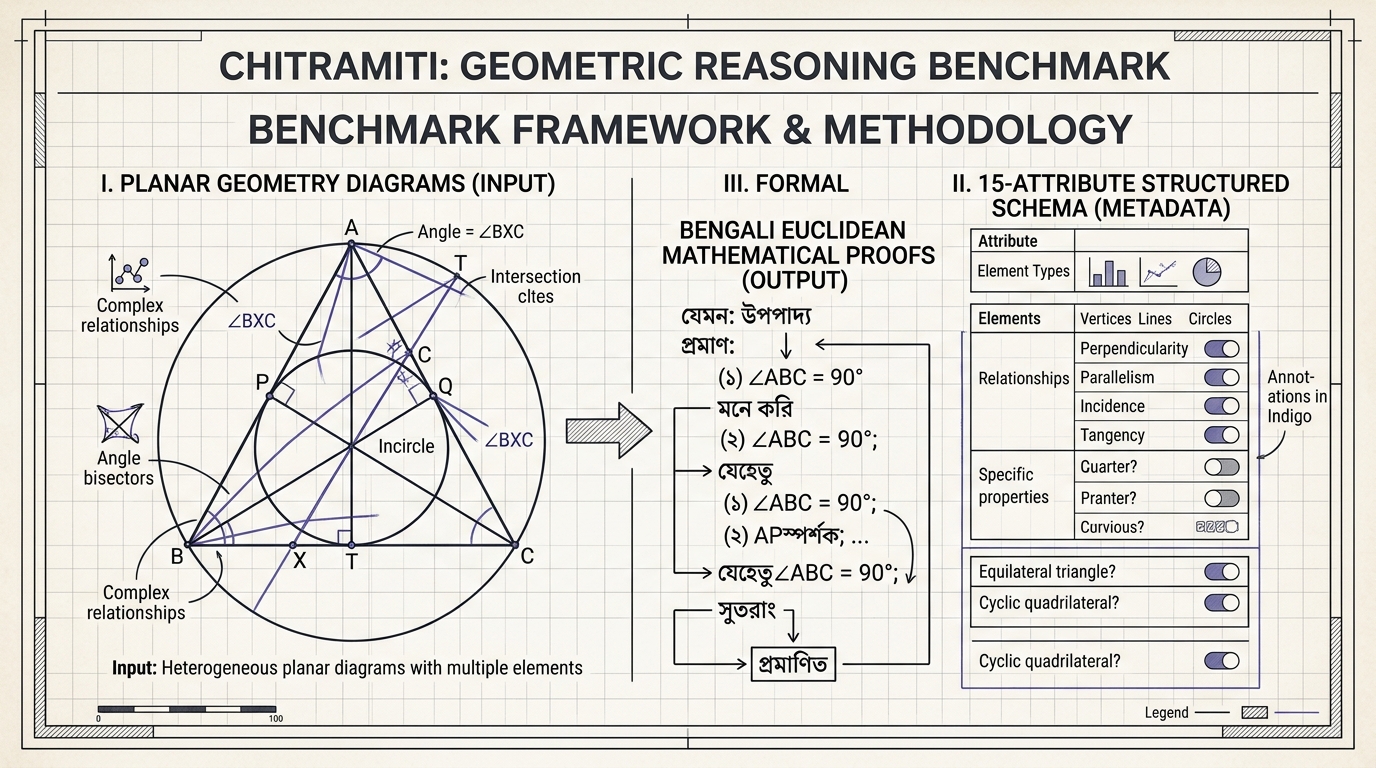
ChitraMiti: Benchmarking Visual Grounding and Modality Reliance in Bengali Geometric Reasoning
Khan Raiyan Ibne Reza, Sanjana Aktar Maria, Sumaiya Tabassum Nimi, Md Adnan Arefeen
Evaluation of vision-language models (VLMs) for multimodal mathematical reasoning remains limited for low-resource languages and for geometry problems that require reading a diagram and a question together. We introduce ChitraMiti-12.8k, a synthetic benchmark of 12,874 Bengali planar geometry problems paired with structured 15-attribute descriptions, and NCTB-500, a complementary set of 500 diagrams manually extracted from Bengali school textbooks. Using a three-phase protocol that separates diagram-only, diagram-plus-description, and description-only inputs, we show across five open-weight and closed-source VLMs that description-only performance is statistically indistinguishable from diagram-plus-description performance, establishing structured descriptions as a sufficient textual proxy for controlled evaluation. Despite this, models remain poor at cross-modal verification, frequently misled by a swapped spatial relation even when they answer the unmodified item correctly. We further evaluate supervised adaptation on ChitraMiti-12.8k, finding that fine-tuning improves performance on both ChitraMiti-1k and NCTB-500, although a substantial gap to the strongest zero-shot model remains. Together, ChitraMiti-12.8k, NCTB-500, and our evaluation protocol offer a standardized way to study Bengali multimodal geometry reasoning and, more broadly, whether VLMs actually check their text against what they see.
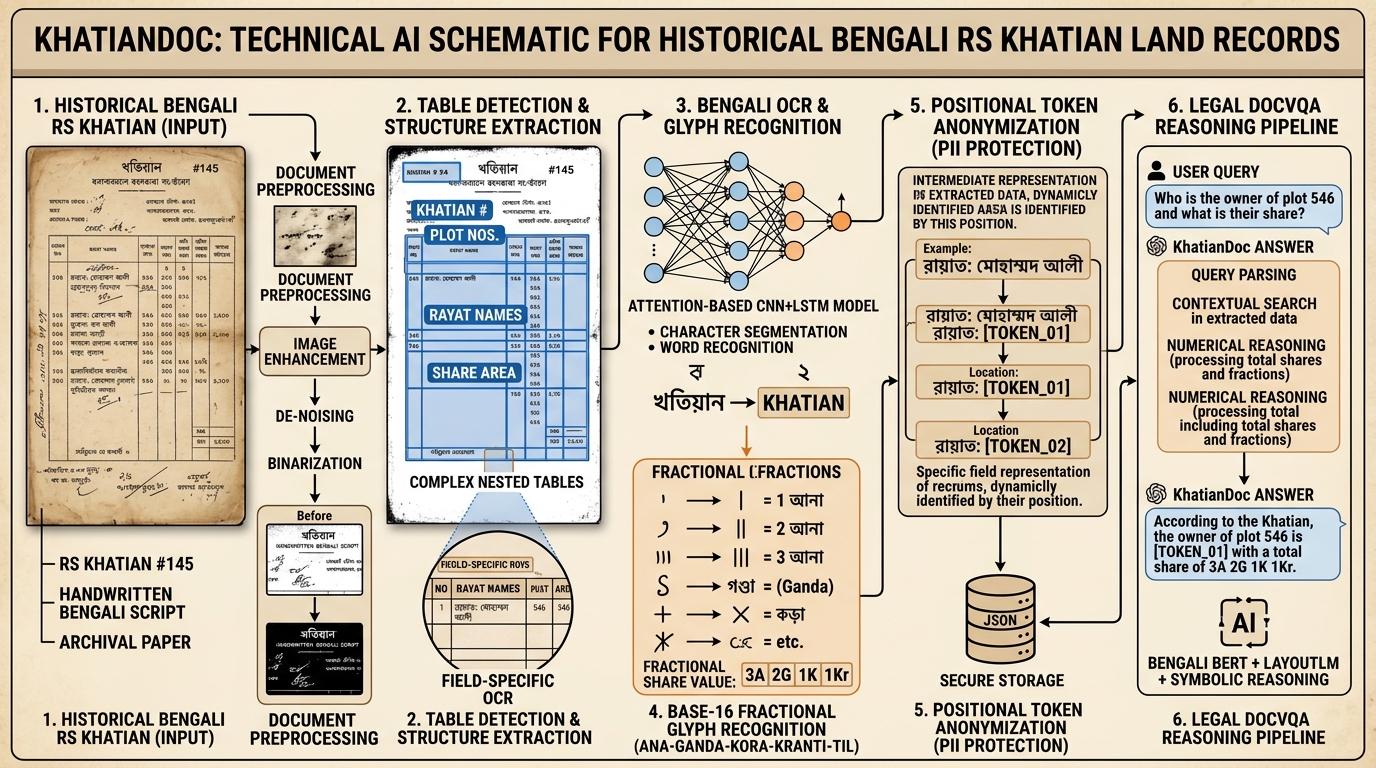
KhatianDoc: A Human-Verified Benchmark Diagnosing Multimodal LLM Failure on Bengali Legal Land Records
Tasmiad Hasan, Arafat Zaman Ratul, Sarker Sadman Saalim, S.M. Shah Nawaz Hossain, Khan Raiyan Ibne Reza, Sumaiya Tabassum Nimi
Land ownership in Bangladesh is recorded in Ana-Ganda-Kora-Kranti-Til, a base-16 positional fraction system with dedicated Unicode glyphs, no mainstream font, and no coverage in any OCR pipeline or tokenizer. The handwritten records that carry these fractions, RS Khatians, are the authoritative title record for millions of parcels and a frequent subject of civil litigation, yet no benchmark has asked whether a machine can read one. We introduce KhatianDoc, a four-task benchmark built from 107 real RS Khatian records from the Vumi (land) Office of Munshiganj, Bangladesh: symbol recognition, base-16-to-decimal conversion, structured field extraction, and legal document question answering over 1,634 QA pairs. Ground truth was transcribed by hand, verified by a land-law practitioner to full agreement, and anonymized through positional tokens that keep the referential distinctions multi-hop questions depend on. We evaluate six multimodal LLMs (8B to 72B+, open and closed) under a fixed zero-shot protocol. Five QA categories, 39.3% of our stratified set, return zero correct answers from every model; on the arithmetic task, every model that emits a number does worse than a constant-mean baseline, with exact- and near-match scores coinciding: decorrelation, not approximation. Auditing our own metrics surfaced two artifacts in opposite directions: we correct a refusal-scoring bug and report the fixed scores beside the originals, and flag an inflated metadata metric as an upper bound. KhatianDoc documents not a performance gap but the absence of a capability, with verified ground truth for future systems.
Four connected research questions
These projects connect evaluation of language, evidence, visual inputs, and efficient model adaptation:
1. Language variation and retrieval
How do dialect, colloquial wording, and cross-language queries change what a retrieval system finds? Agricultural advisory work tests retrieval across these query conditions.
2. Evidence grounding and safety
Can a system preserve source evidence and avoid unsafe recommendations in agricultural advice? KrishokChat studies provenance, refusal, and chemical-advisory reliability. KrishokTech turns those findings into ordered runtime controls that can ask, confirm, refer, or drop before advice is delivered.
3. Visual and document understanding
Do multimodal models use diagrams and document structure, or rely on language priors? ChitraMiti and KhatianDoc evaluate Bengali geometry and land records.
4. Efficient educational models
Can tutoring and physics capabilities transfer to smaller models that work offline? TRACE-BN and PhysicsMate examine curriculum-grounded adaptation for Bengali learners.
Access Curated Hugging Face Datasets & Leaderboards
Download our verified Bengali benchmarks, training splits, and evaluation harnesses to test your own models against these failure modes.
Evaluating this work?
Raw evaluation logs, unredacted manuscripts, and custom benchmark runs are available on request for peer reviewers and graduate admissions evaluation.